Topics
A null hypothesis is not “nothing is happening.” It is a mathematical restriction on the data-generating model. Examples include
or
A statistical test asks whether the observed data are sufficiently incompatible with that restriction according to a chosen test statistic. The phrase chosen test statistic matters. Different statistics detect different kinds of departure.
A p-value is conditional on the null model
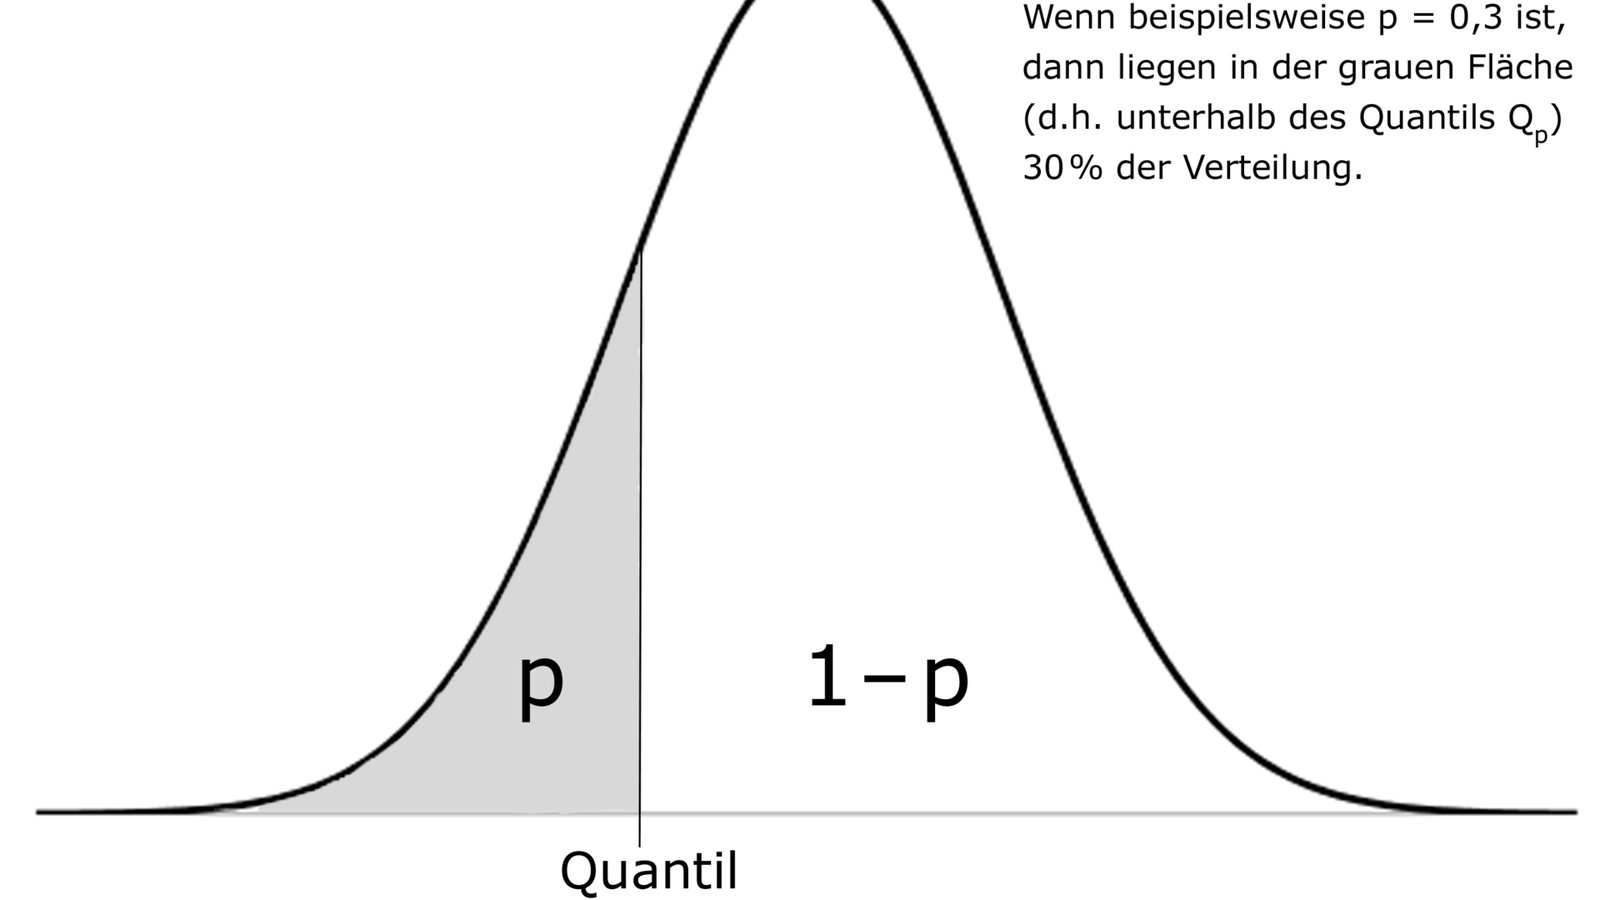
Let $T(X)$ be a statistic where larger values are more incompatible with $H_0$. The p-value is
with modifications for two-sided or discrete tests. The probability is computed under the null model. It is not
Frequentist testing does not assign a posterior probability to the null hypothesis without adding a prior and a Bayesian model.
Non-rejection is not acceptance
If
the data did not cross the chosen rejection threshold. That can occur because:
- the null is approximately true;
- the alternative effect is small;
- the sample is too small;
- the measurement is noisy;
- the test is insensitive to the actual departure;
- the design contains little information.
Therefore
Equivalence is a different hypothesis
Suppose effects smaller than $\Delta$ are practically negligible. An equivalence question is not
A common equivalence formulation is
against
Now rejection supports the claim that the effect lies within the equivalence margin. This reverses the usual logic. A non-significant ordinary superiority test is not an equivalence test.
Test statistics encode sensitivity
Consider testing whether a distribution equals a reference $F_0$. The Kolmogorov-Smirnov statistic uses
It is especially sensitive to the largest CDF discrepancy. Anderson-Darling applies greater tail weight. Shapiro-Wilk uses ordered observations and is designed specifically for normality. These procedures can produce different p-values from the same sample because they weight departures differently. That is not a contradiction. They are asking different discrepancy questions.
Omnibus tests trade specificity for breadth
An omnibus test can detect many kinds of departure. The price is that rejection often does not identify the mechanism. For example, a chi-square test of independence can reject because several cells differ from expectation. The scalar statistic does not say which association pattern matters. A residual analysis or targeted contrast is needed afterward.
Targeted tests can have greater power when the alternative is specified in advance.
Power depends on the alternative
For parameter value $\theta$, define
This is the power function. There is no single number called “the power” unless a particular alternative or distribution over alternatives is specified. A normality test can have high power against heavy tails and lower power against a mild mixture. A mean test can have almost no power against a pure variance change. Sensitivity follows the statistic.
Large samples detect small departures
Suppose the null is not exactly true but differs only slightly from reality. As $n$ increases, many consistent tests will eventually reject. This can produce
for a discrepancy too small to matter scientifically. Statistical significance therefore does not measure practical importance. Effect size and uncertainty remain necessary.
Small samples hide meaningful departures
The reverse problem occurs in small samples. A large clinically relevant effect can remain non-significant because the estimate is imprecise. This is why interpretation should include the confidence interval. An interval such as
contains zero but also contains effects that may be scientifically important. The p-value alone hides that.
Model assumptions sit underneath the test
A p-value is valid only under the assumptions used to derive its null distribution. Those may include:
- independence;
- randomization;
- distributional form;
- variance assumptions;
- censoring assumptions;
- asymptotic approximation;
- correct model specification.
A precisely computed p-value from the wrong null distribution is still wrong.
Multiple testing changes the reference problem
If a researcher tries many analyses and reports only the smallest p-value, the nominal null calibration no longer describes the selection procedure. The relevant probability becomes conditional on the entire search process. Multiplicity corrections, selective-inference methods, preregistration, or held-out confirmation can address different parts of this problem.
The unit of inference is the procedure, not one number extracted after the fact.
Bayesian inference answers another question
Bayesian inference assigns a prior
and updates it through the likelihood:
Now posterior probabilities such as
are meaningful inside the Bayesian model. That is not a repaired p-value. It is a different inferential framework with different assumptions.
Confidence intervals and tests are linked
For many standard procedures, a two-sided level-$\alpha$ test rejects
exactly when the corresponding
confidence interval excludes $\theta_0$. The interval is usually more informative because it displays a range of parameter values compatible with the procedure. It still should not be interpreted as a posterior probability interval.
A practical reporting standard
Instead of writing only
$p=0.03$, statistically significant,
report:
- the estimand;
- the effect estimate;
- the uncertainty interval;
- the test and statistic;
- the p-value if relevant;
- assumptions and design;
- practical or scientific scale.
This makes it much harder for the threshold to replace the scientific argument.
Conclusion
A null hypothesis is a restriction on a model. A test measures discrepancy from that restriction through a chosen statistic. The correct chain is
Non-rejection is not proof of the null. Rejection is not proof of importance. The value of a test comes from knowing what departure it is capable of detecting and what scientific claim that departure represents.
References
- Neyman, J., & Pearson, E. S. (1933). On the problem of the most efficient tests of statistical hypotheses. Philosophical Transactions of the Royal Society A, 231, 289–337.
- Wasserstein, R. L., & Lazar, N. A. (2016). The ASA statement on p-values: context, process, and purpose. The American Statistician, 70(2), 129–133.
- Greenland, S., Senn, S. J., Rothman, K. J., et al. (2016). Statistical tests, P values, confidence intervals, and power: a guide to misinterpretations. European Journal of Epidemiology, 31, 337–350.
Embed interactive plots, widgets, and demos using <figure>, <iframe>, or <div class="interactive-embed"> containers. Ensure each embed includes descriptive captions for accessibility.
How to cite
Use the quick export buttons to save citations for reference managers or copy the formatted text directly.
Diogo Ribeiro (2020). The Null Hypothesis: Compatibility, Power, and Test Sensitivity. Faculty of Media Arts and Design, Technical University of Porto. https://diogoribeiro7.github.io/statistics/understanding_statistical_testing_null_hypothesis_beyond/.